Upload date
All time
Last hour
Today
This week
This month
This year
Type
All
Video
Channel
Playlist
Movie
Duration
Short (< 4 minutes)
Medium (4-20 minutes)
Long (> 20 minutes)
Sort by
Relevance
Rating
View count
Features
HD
Subtitles/CC
Creative Commons
3D
Live
4K
360°
VR180
HDR
383 results
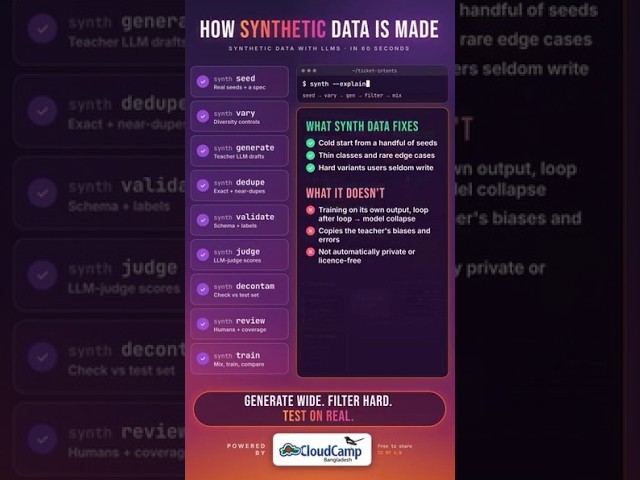
How can AI models generate synthetic training data, and how do developers ensure that the generated examples are useful?
61 views
5d ago
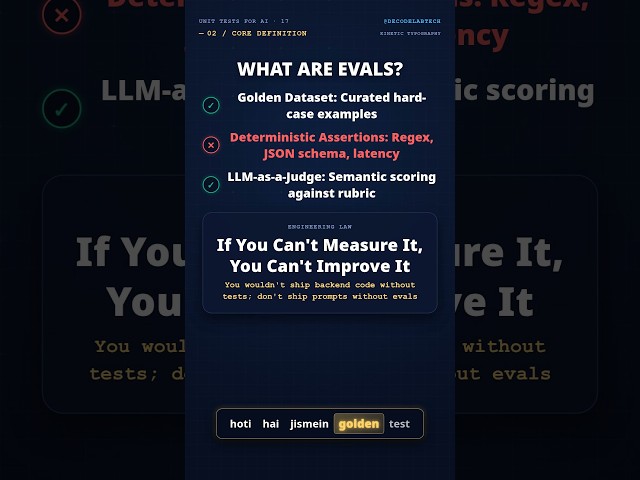
Never deploy prompt changes based on a "vibe check". Discover how AI Evals create automated test suites for LLM apps in 50 ...
51 views
2d ago
Your AI agent gave the right answer. So why did it fail? In this short, you'll learn the 5 AI testing metrics teams are using in 2026 ...
157 views
6d ago
How do you know your LLM app actually works? It's one of the most asked AI interview questions. And if your answer is "I tried a ...
182 views
7d ago
https://docs.google.com/document/d/1McXSKtQYrFadie2HnOK1BmzZfHGfbDETfHZsDPdFepo/edit?usp=sharing AI testing ...
311 views
4d ago
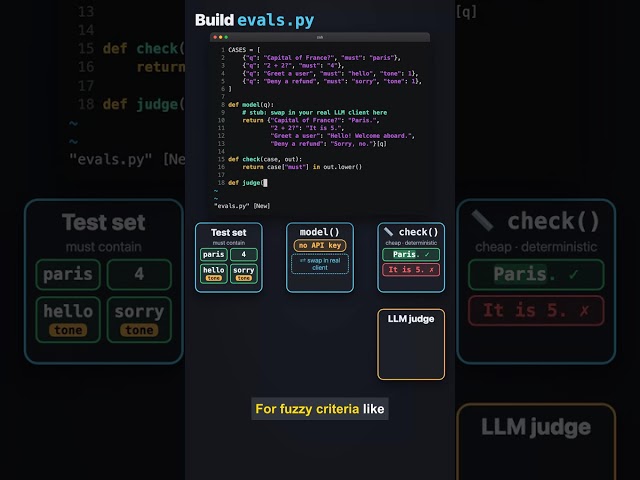
Changing a prompt without evals is just a vibe check. In this short, we build a tiny Python eval harness that treats LLM evals like ...
58 views
1d ago
Explore LLM Application Development with Britixo. This animated service overview follows requirements, scope, architecture and ...
0 views
How to Test If Your AI Actually Works (Evals) — a 30-second preview of Episode 17 of the free AI & LLM Fundamentals course.
10 views
How to measure an AI judge before you trust it. Take 10-20 answers your system gave and mark each pass or fail by hand.
42 views
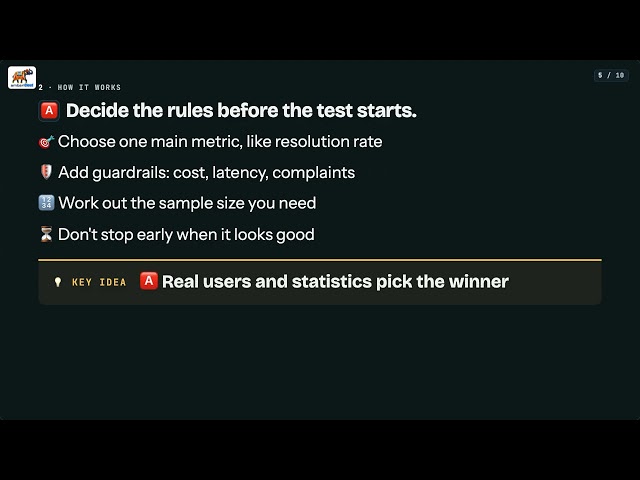
Split traffic, measure the outcome that matters, and check it isn't luck. Video 7 of 8 in the Evaluation & Quality section of AI ...
2 views
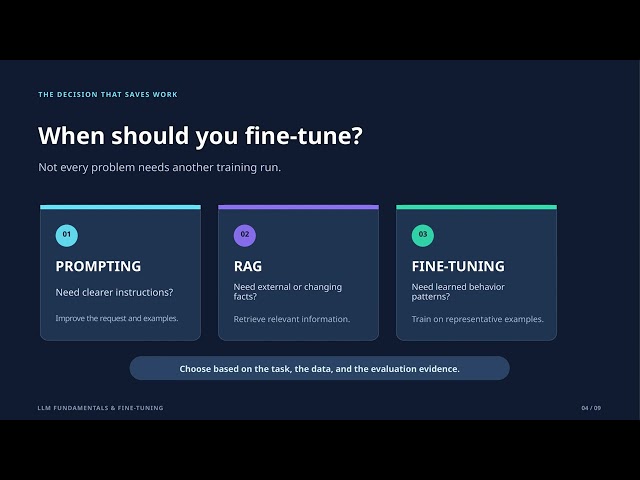
Link: https://www.udemy.com/course/llm-fundamentals-fine-tuning-from-theory-to-practice/?
93 views
3d ago
Can one AI grade another? Mostly yes, with a catch. In the MT-Bench study a strong model agreed with human markers over 80% ...
33 views
Write your first 20-question eval set. Four kinds, five each: exact part numbers, our own words, part numbers typed oddly, and only ...
14 views
Stop manually testing AI prompts and start building automated CI/CD pipelines. Learn how to integrate tools like promptfoo and ...
11 views
Learn how to red team LLMs at scale before malicious hackers break your production AI. In this video, we cover structured ...
13 views
Automated Prompt Regression Testing with Pytest and LLM-as-a-Judge #Shorts Preventing silent accuracy degradation when ...
28 views
Why pay for the same AI response multiple times when you can reuse it? Caching helps reduce LLM costs by storing frequently ...
46 views
Can your LLM tests run without calling the model? If not, they're slow and flaky and get skipped. Why it matters: a version of our ...
113 views
Is your LLM vulnerable to jailbreaks and prompt injections? In this quick guide, you will learn how to test your AI applications ...
How do you test an AI that never answers the same way twice? With evals and LLM-as-judge. Priya fixed one prompt and quietly ...
281 views